
Scalable Segment and Subsegment Structure in HubSpot
How we standardized industry segmentation across five HubSpot objects, including two custom objects, and migrated every legacy sub-industry value into a clean, segment-specific model.
Project Overview
The client uses HubSpot as the central system for relationship and pipeline management. Every record is classified by industry on two levels: a Segment, such as Healthcare or Software, and a Sub-Segment that provides a more precise classification. This structure drives list segmentation, deal and project reporting, team routing, and the matching of opportunities with the right experts.
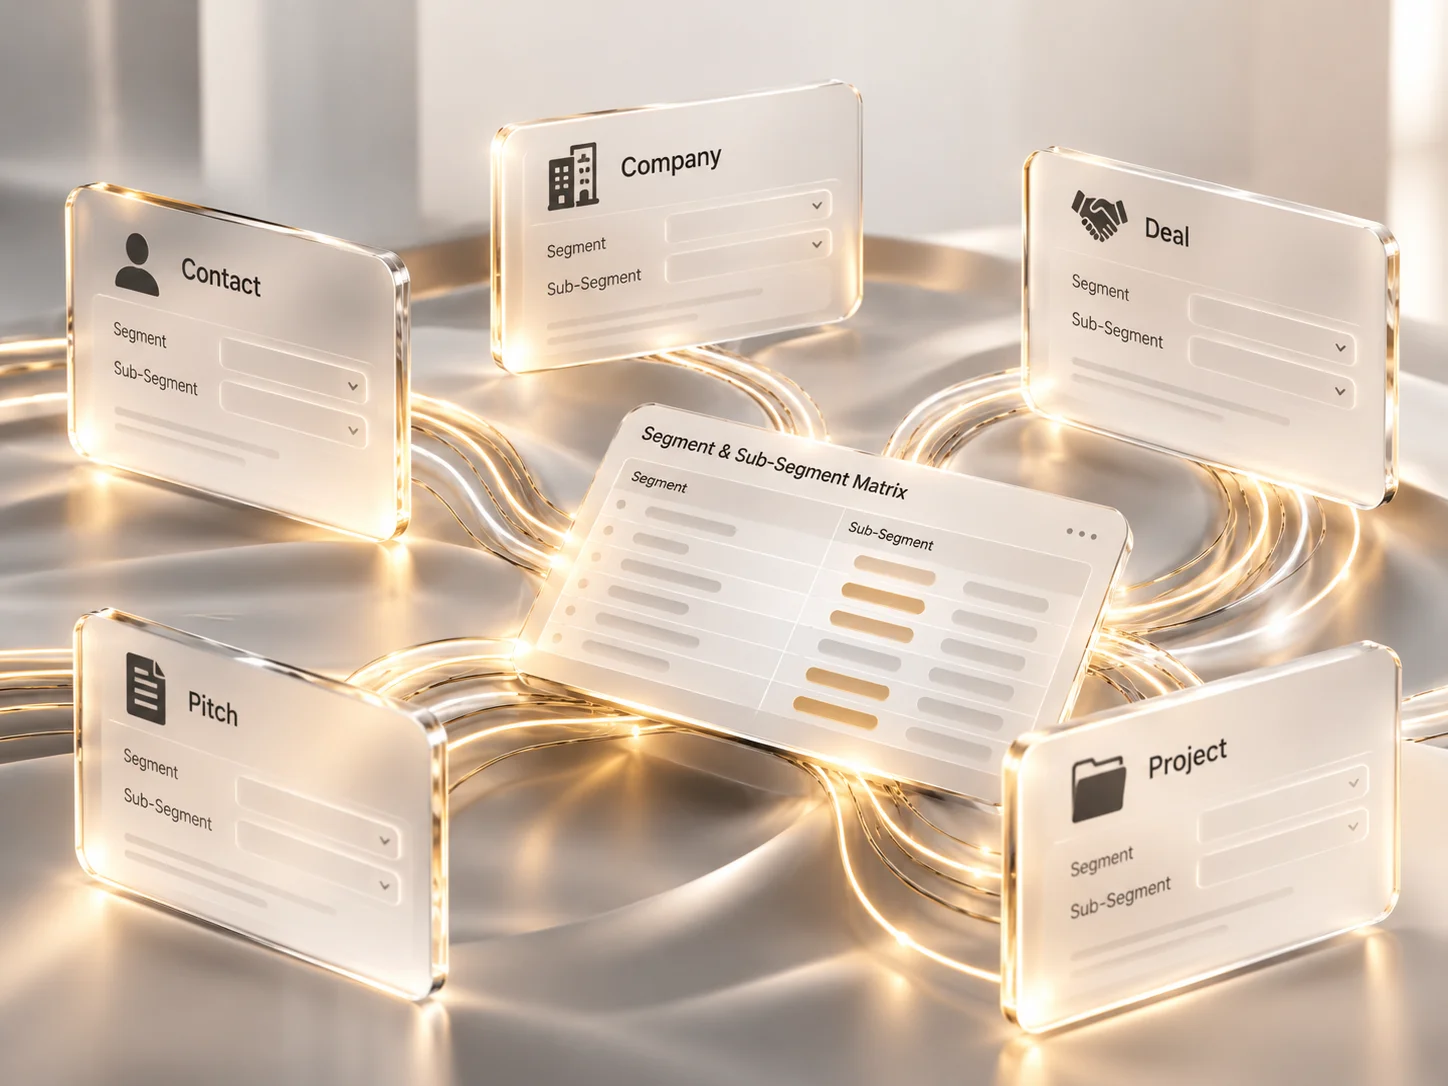
The classification was required across five objects: Contacts, Companies, Deals, and the two custom objects Pitches and Projects. Over time, the data model had evolved organically rather than by design, and the team could no longer rely on it.
Customer Challenge
The existing setup had several structural problems. The portal did not include HubSpot Data Hub. This ruled out custom-code workflow actions, data-quality automation, and formula-based transformations inside HubSpot.
Each multi-select value had to be split and routed into one of seven target properties. With standard workflows, this would have required one branch per sub-industry option on every object, making the setup unmaintainable from day one.
Some records already contained values in the new properties. The migration had to add values without overwriting existing information and remain safe to run more than once. The client needed to see exactly what would change before any data was written, together with a complete audit trail after the migration. Any external tool had to respect HubSpot rate limits and recover from errors without losing track of progress.
Initial Situation
The first options we evaluated all fell short. The client classifies every record by Segment and Sub-Segment across Contacts, Companies, Deals, and the two custom objects Pitches and Projects. This classification drives segmentation, reporting, team routing, and expert matching.
On Companies, every sub-industry from every segment was mixed into one long multi-select. Nothing connected a sub-industry with its segment, so mismatched records often went unnoticed until reports produced inconsistent results.
The same classification was modelled differently on each object. As a result, a Healthcare filter on Deals did not mean the same thing as a Healthcare filter on Companies. Older values also contained inconsistent casing and stray whitespace. Reports required manual reconciliation, workflows relied on unreliable fields, and users gradually stopped using the classification.
Solution
The client defined seven segments and the valid sub-segments for each one. Every legacy value was mapped to exactly one segment and one canonical option, including corrections for duplicates, spelling errors, and outdated names.
Each segment received its own multi-select property containing only its valid options. Option values were aligned with the legacy values, so the mapping remains visible and maintainable directly in HubSpot.
A small Node.js script moved legacy values into the new properties through the HubSpot CRM API. It loads the allowed options, retrieves all companies, builds and previews every update, then writes the approved changes and exports an audit CSV.
The same properties were mirrored on Contacts, Deals, Pitches, and Projects. Standard HubSpot workflows keep associated records aligned with their company, without custom code inside HubSpot.
The build was intentionally minimal: one JavaScript file with axios as its only dependency, authenticated through a HubSpot private app token. It uses the Properties API to read options and the Objects API to retrieve and update companies, with automatic retries for rate limits and server errors. Nothing was installed in the portal, so the solution works on any HubSpot tier that supports custom properties.
The script matches values against live option definitions instead of guessing, merges new values with existing ones so nothing is overwritten, and always runs a dry run before client review. Unmatched values are logged as a to-do list instead of being dropped, and every run creates a complete audit CSV that explains why each record holds its value.
Business Value / Outcome


